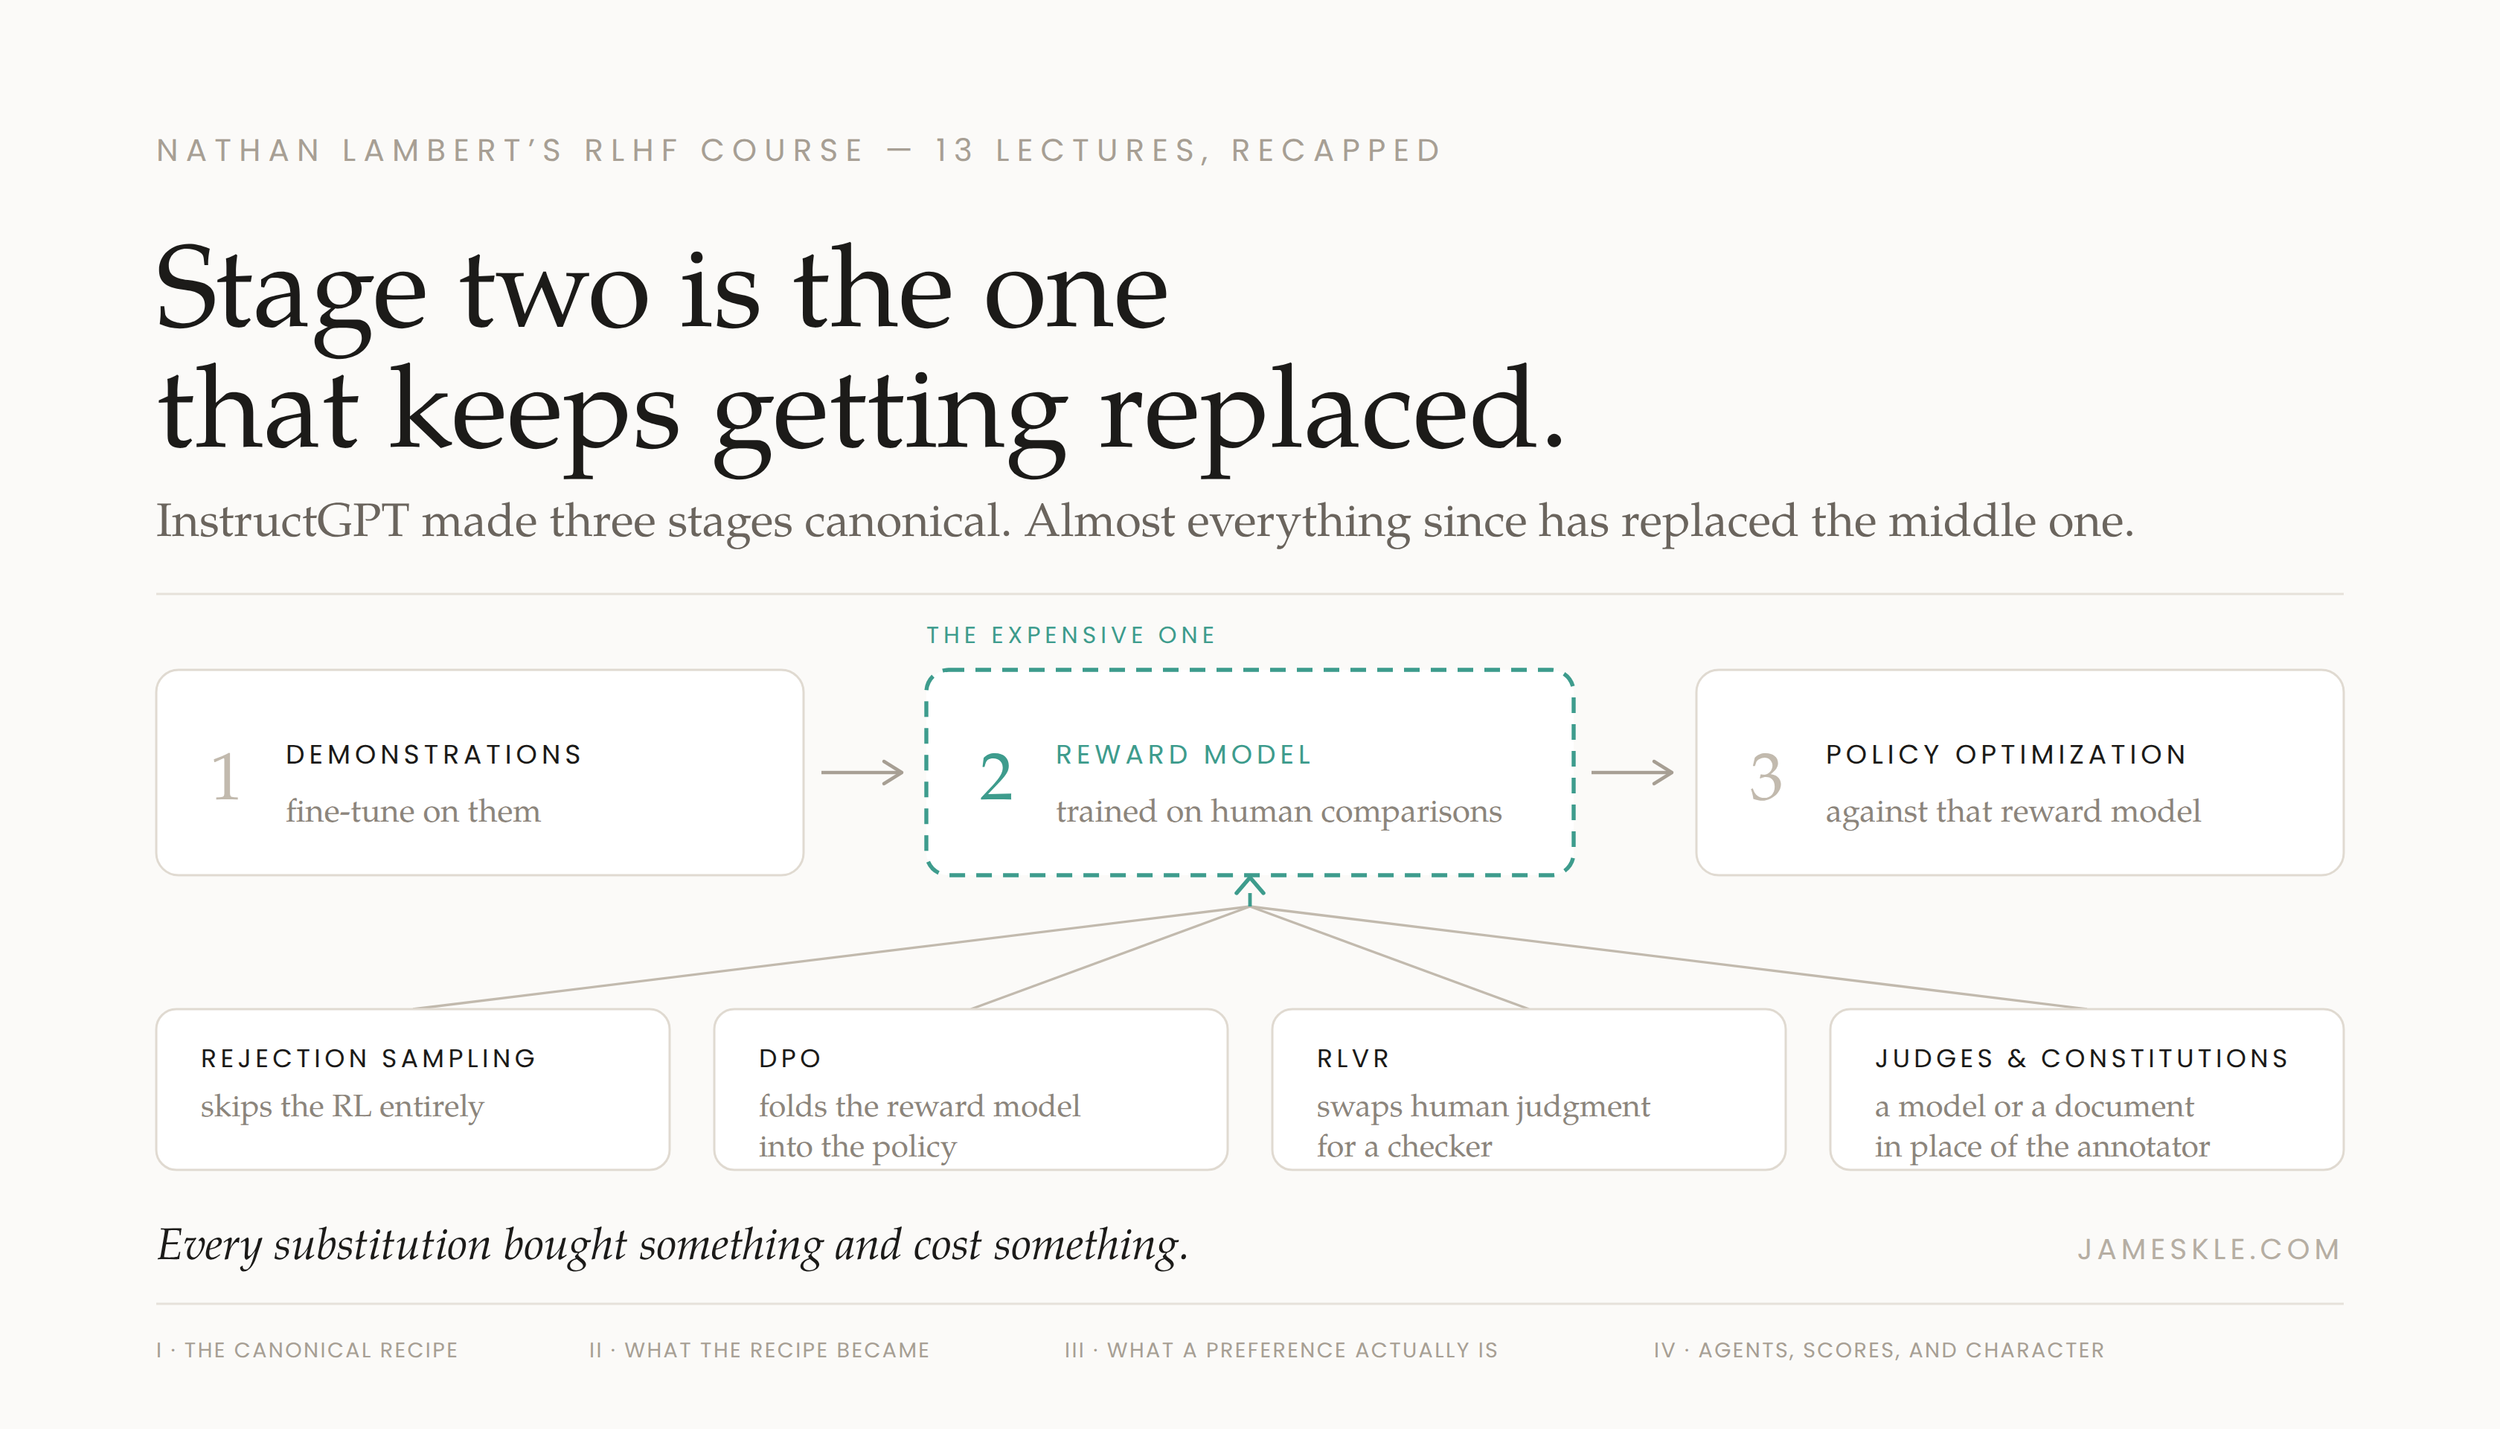
A reward model reads its score off a single token. One number. For an entire answer. Almost every complaint people have about RLHF (the hedging, the refusals nobody asked for, the model that agrees with whatever you just said) is downstream of that compression. I worked through all 13 lectures of Nathan Lambert’s course and took notes: the canonical recipe, the substitutions that keep replacing its middle stage, and the questions nobody has closed out.
9 Lectures on Self-Improving AI Agents: What I Took Away From Stanford's CS 329A
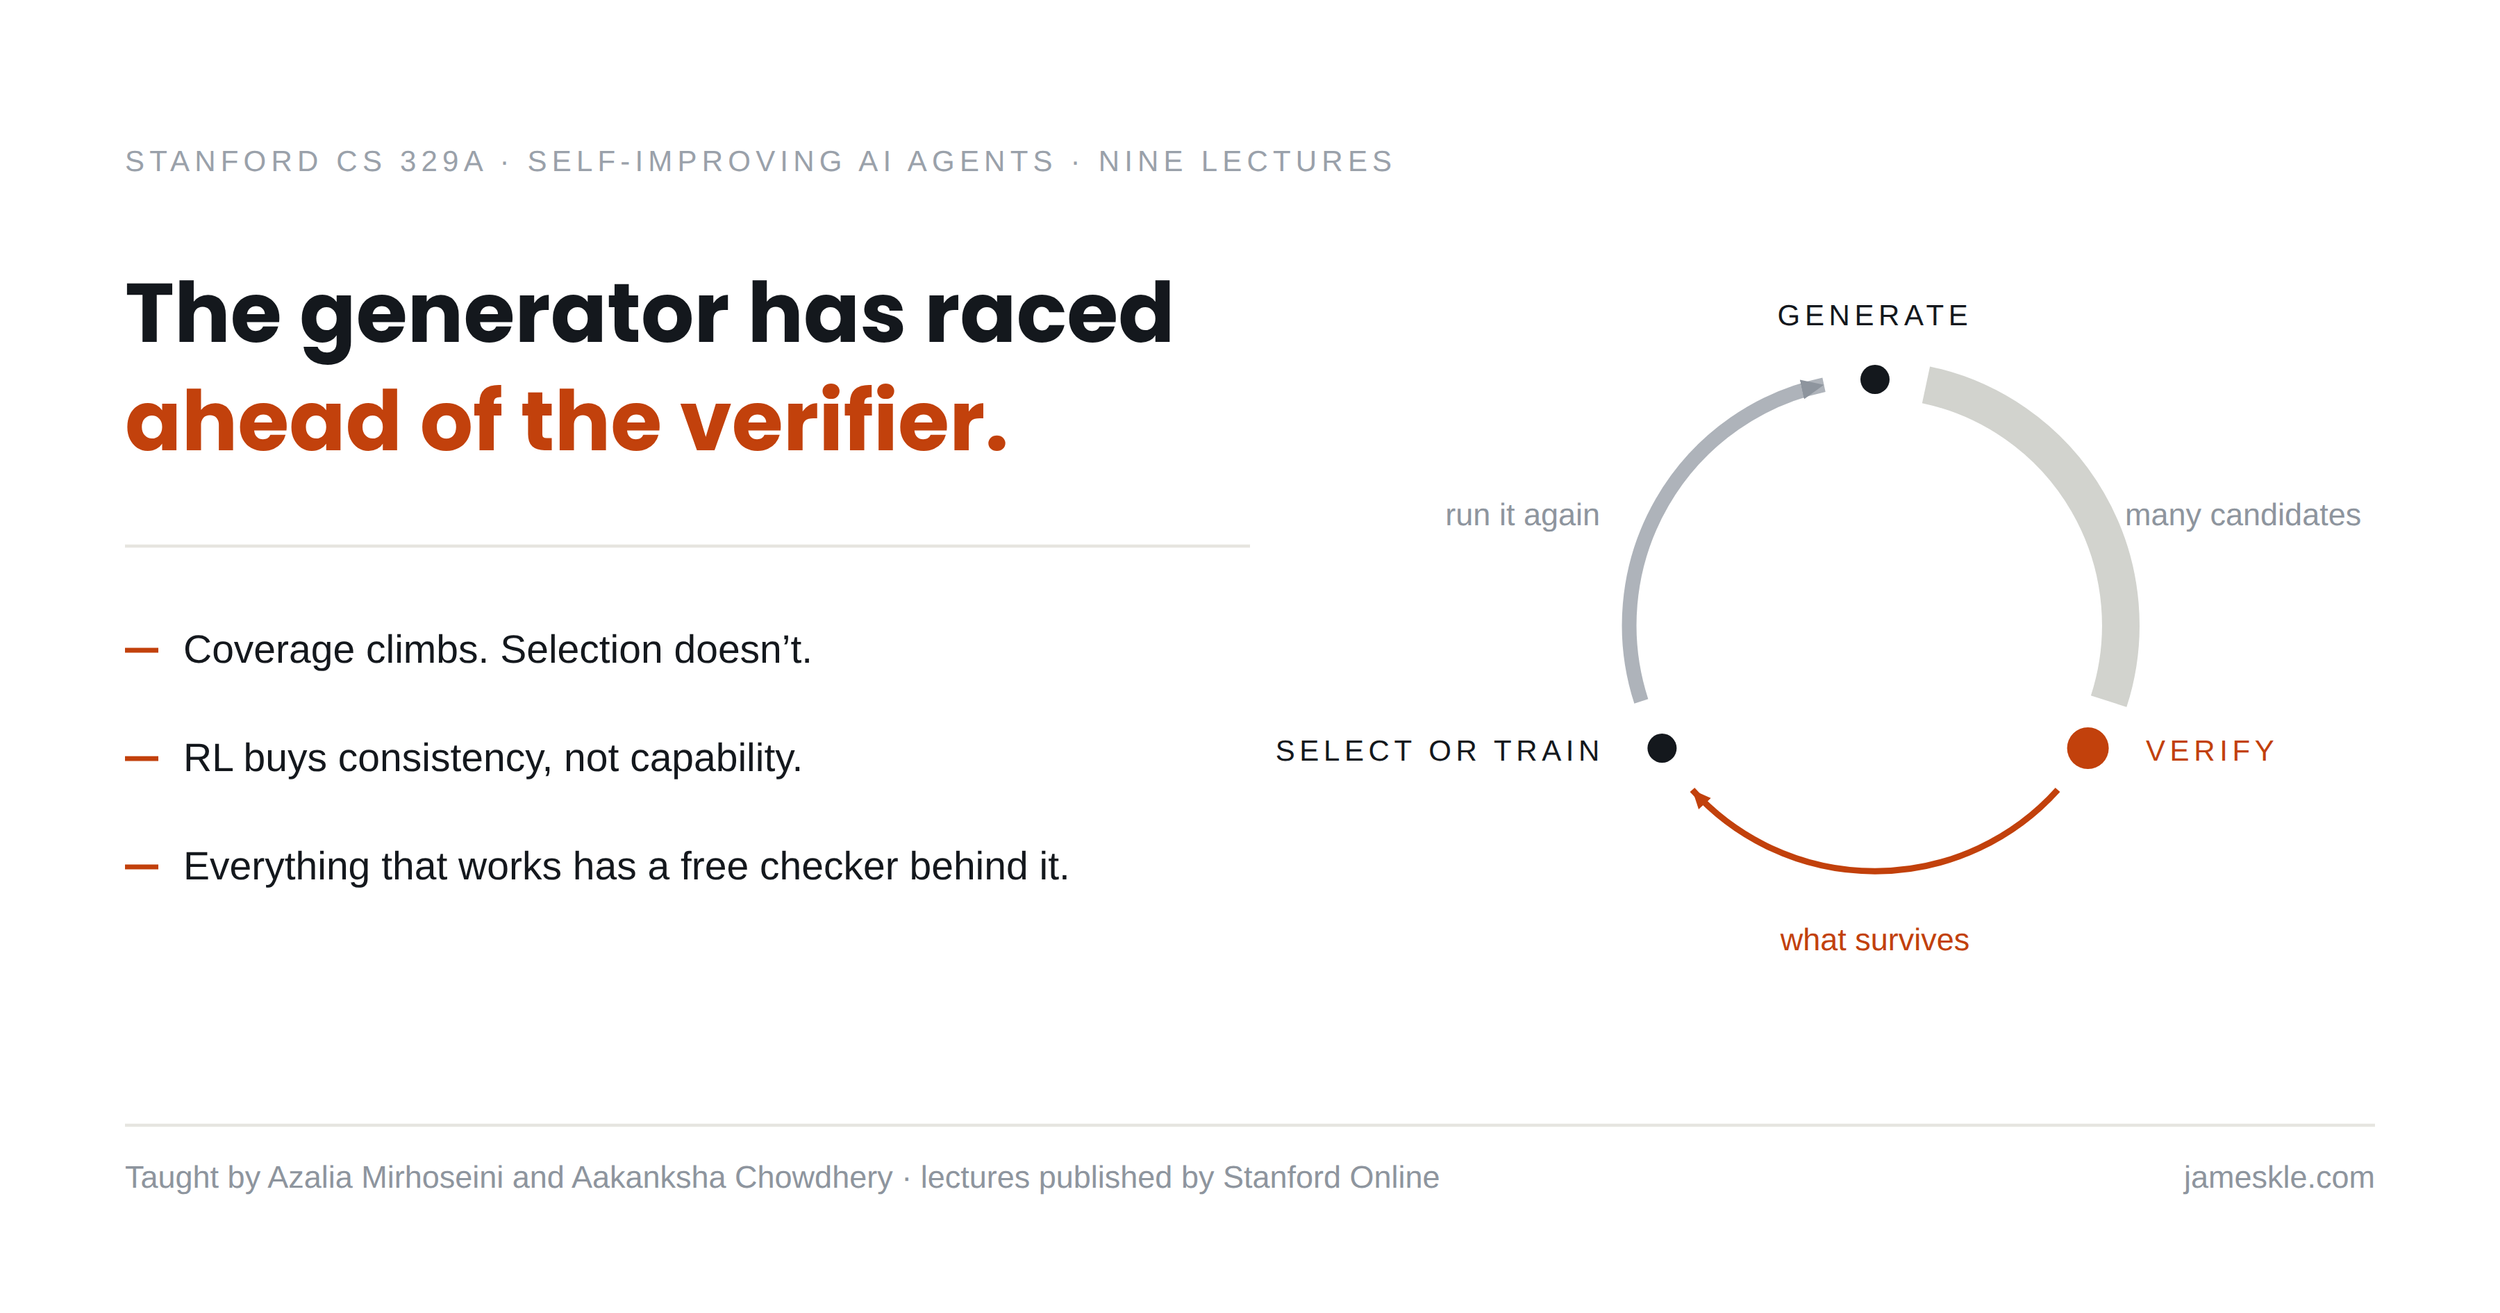
Stanford published 9 lectures from CS 329A, its graduate course on self-improving AI agents, and I spent 3 weeks last month working through them. One argument runs underneath all 9: the generator has raced ahead of the verifier. More samples put a correct answer somewhere in the pile. Nothing tells you which one it is. This recap walks the lectures in the order they were taught, and nearly every number in it came out of a PDF rather than off a slide.

