
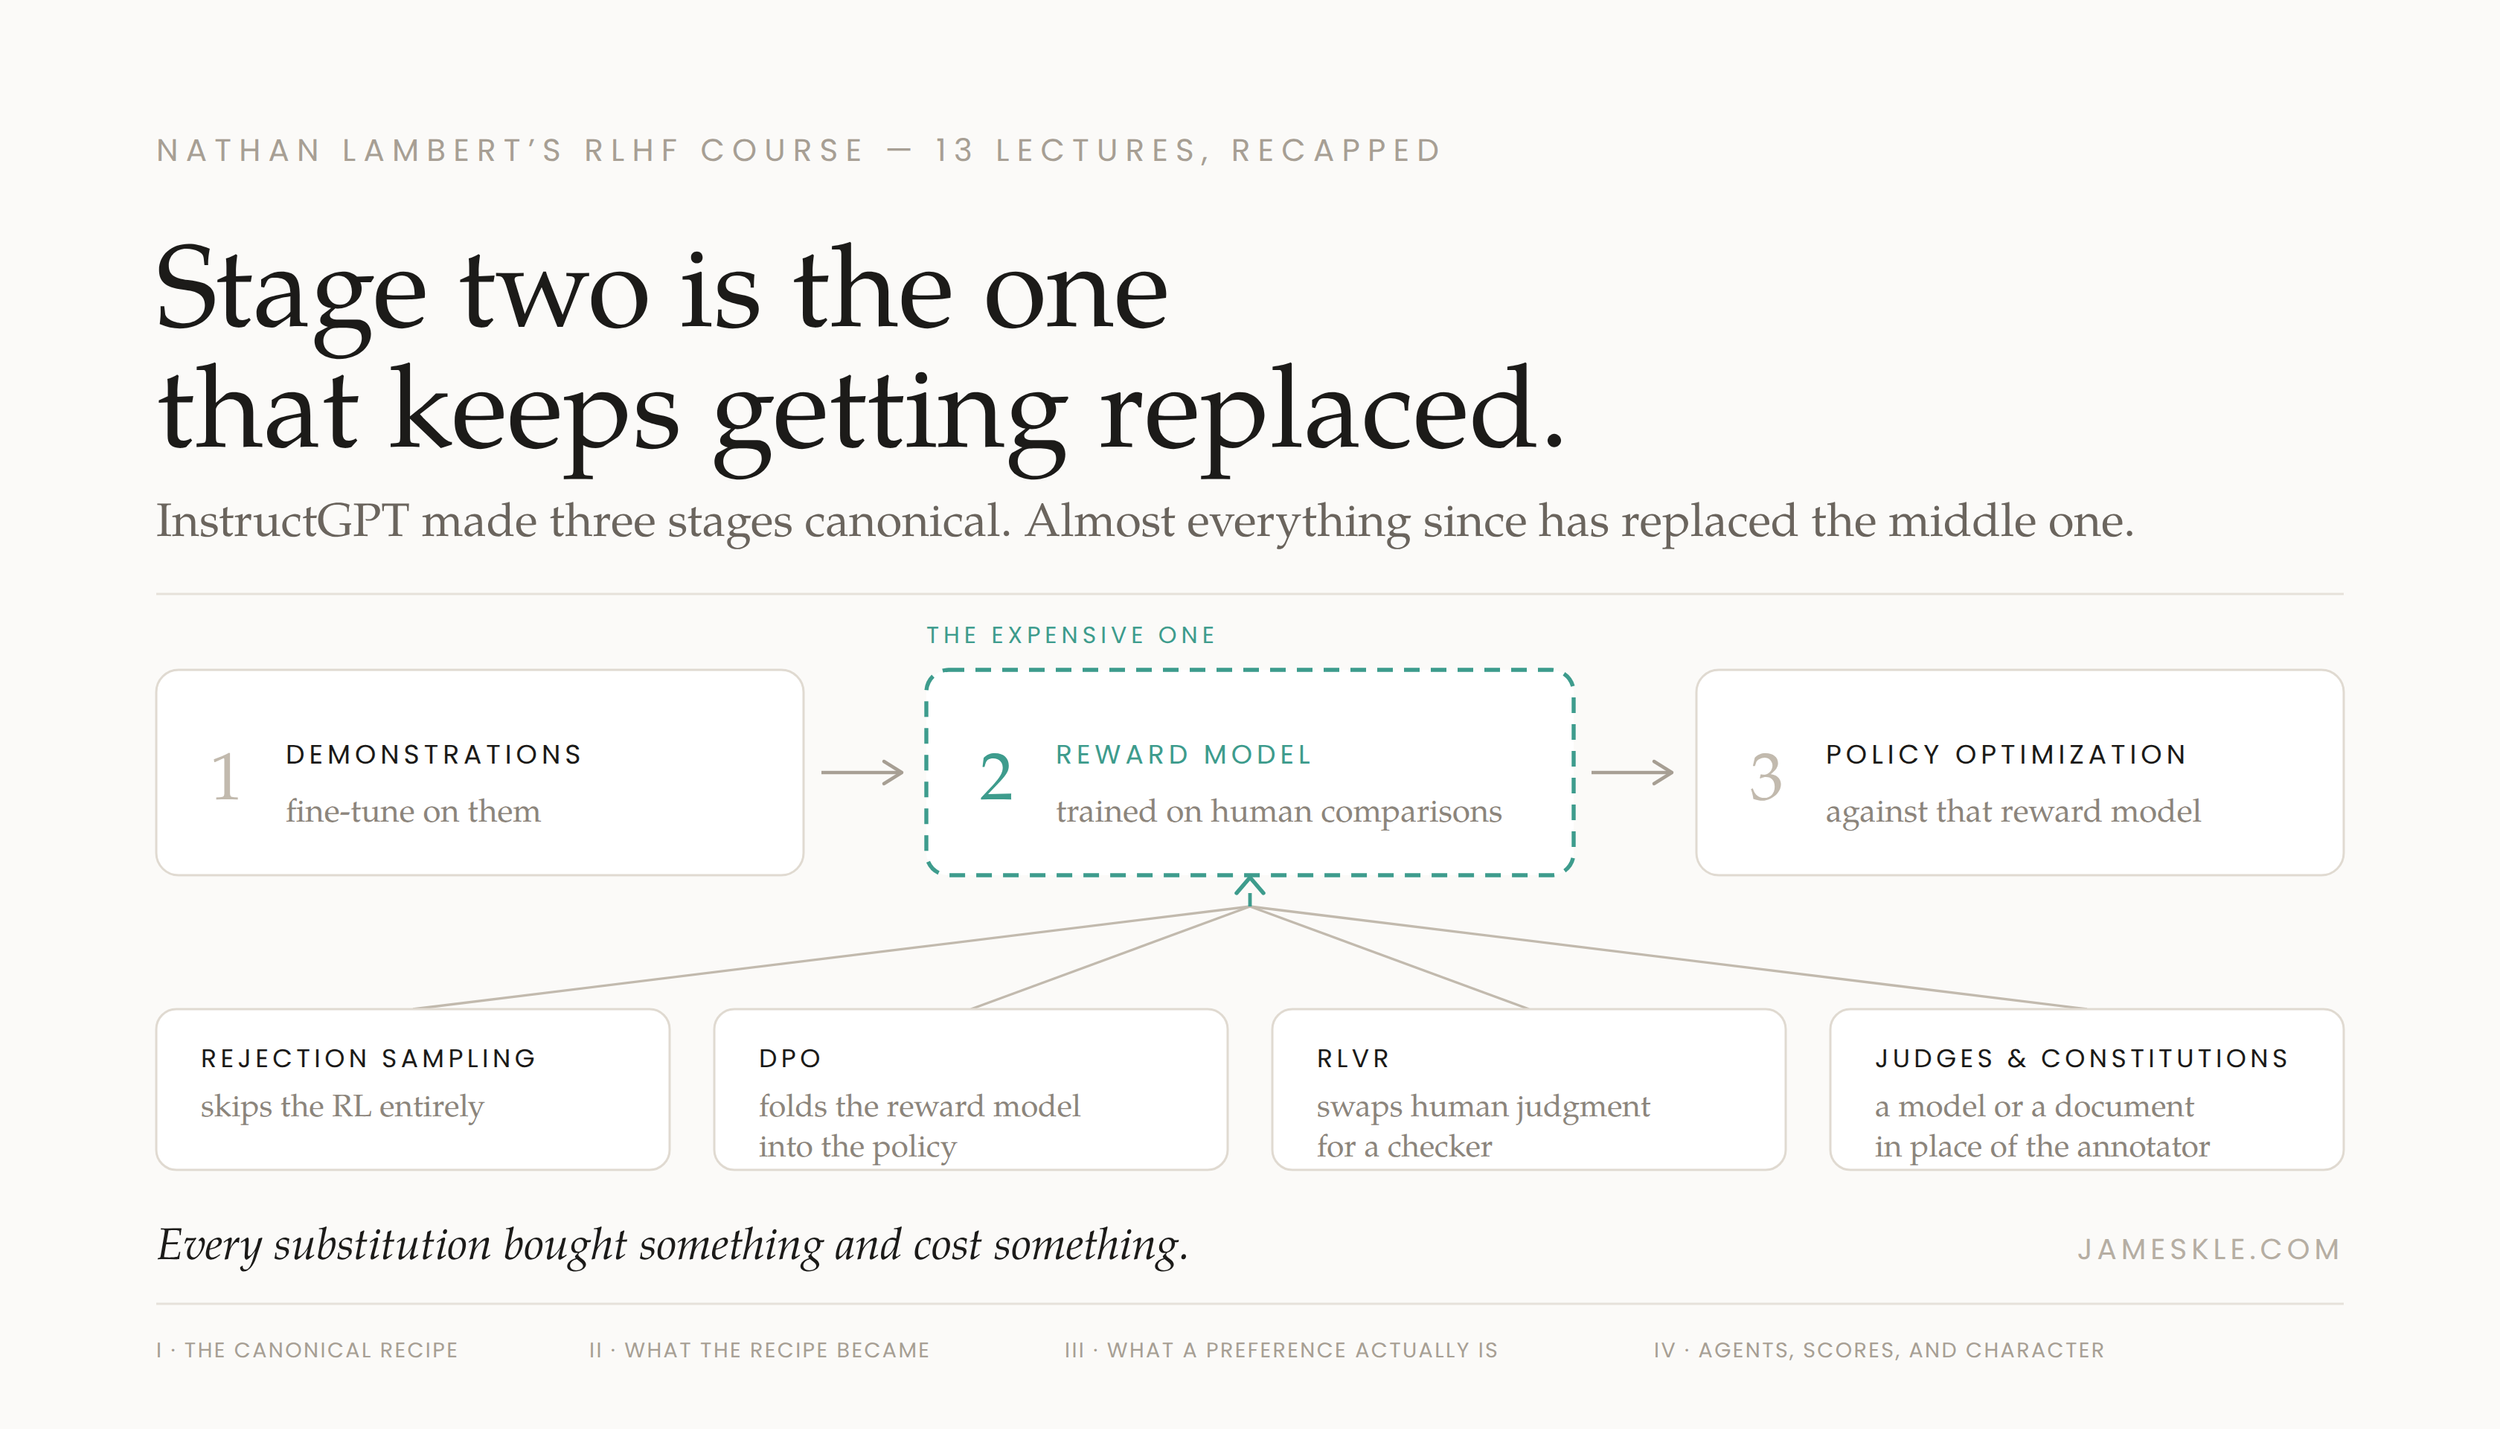
A reward model reads its score off a single token. One number. For an entire answer. Almost every complaint people have about RLHF (the hedging, the refusals nobody asked for, the model that agrees with whatever you just said) is downstream of that compression. I worked through all 13 lectures of Nathan Lambert’s course and took notes: the canonical recipe, the substitutions that keep replacing its middle stage, and the questions nobody has closed out.