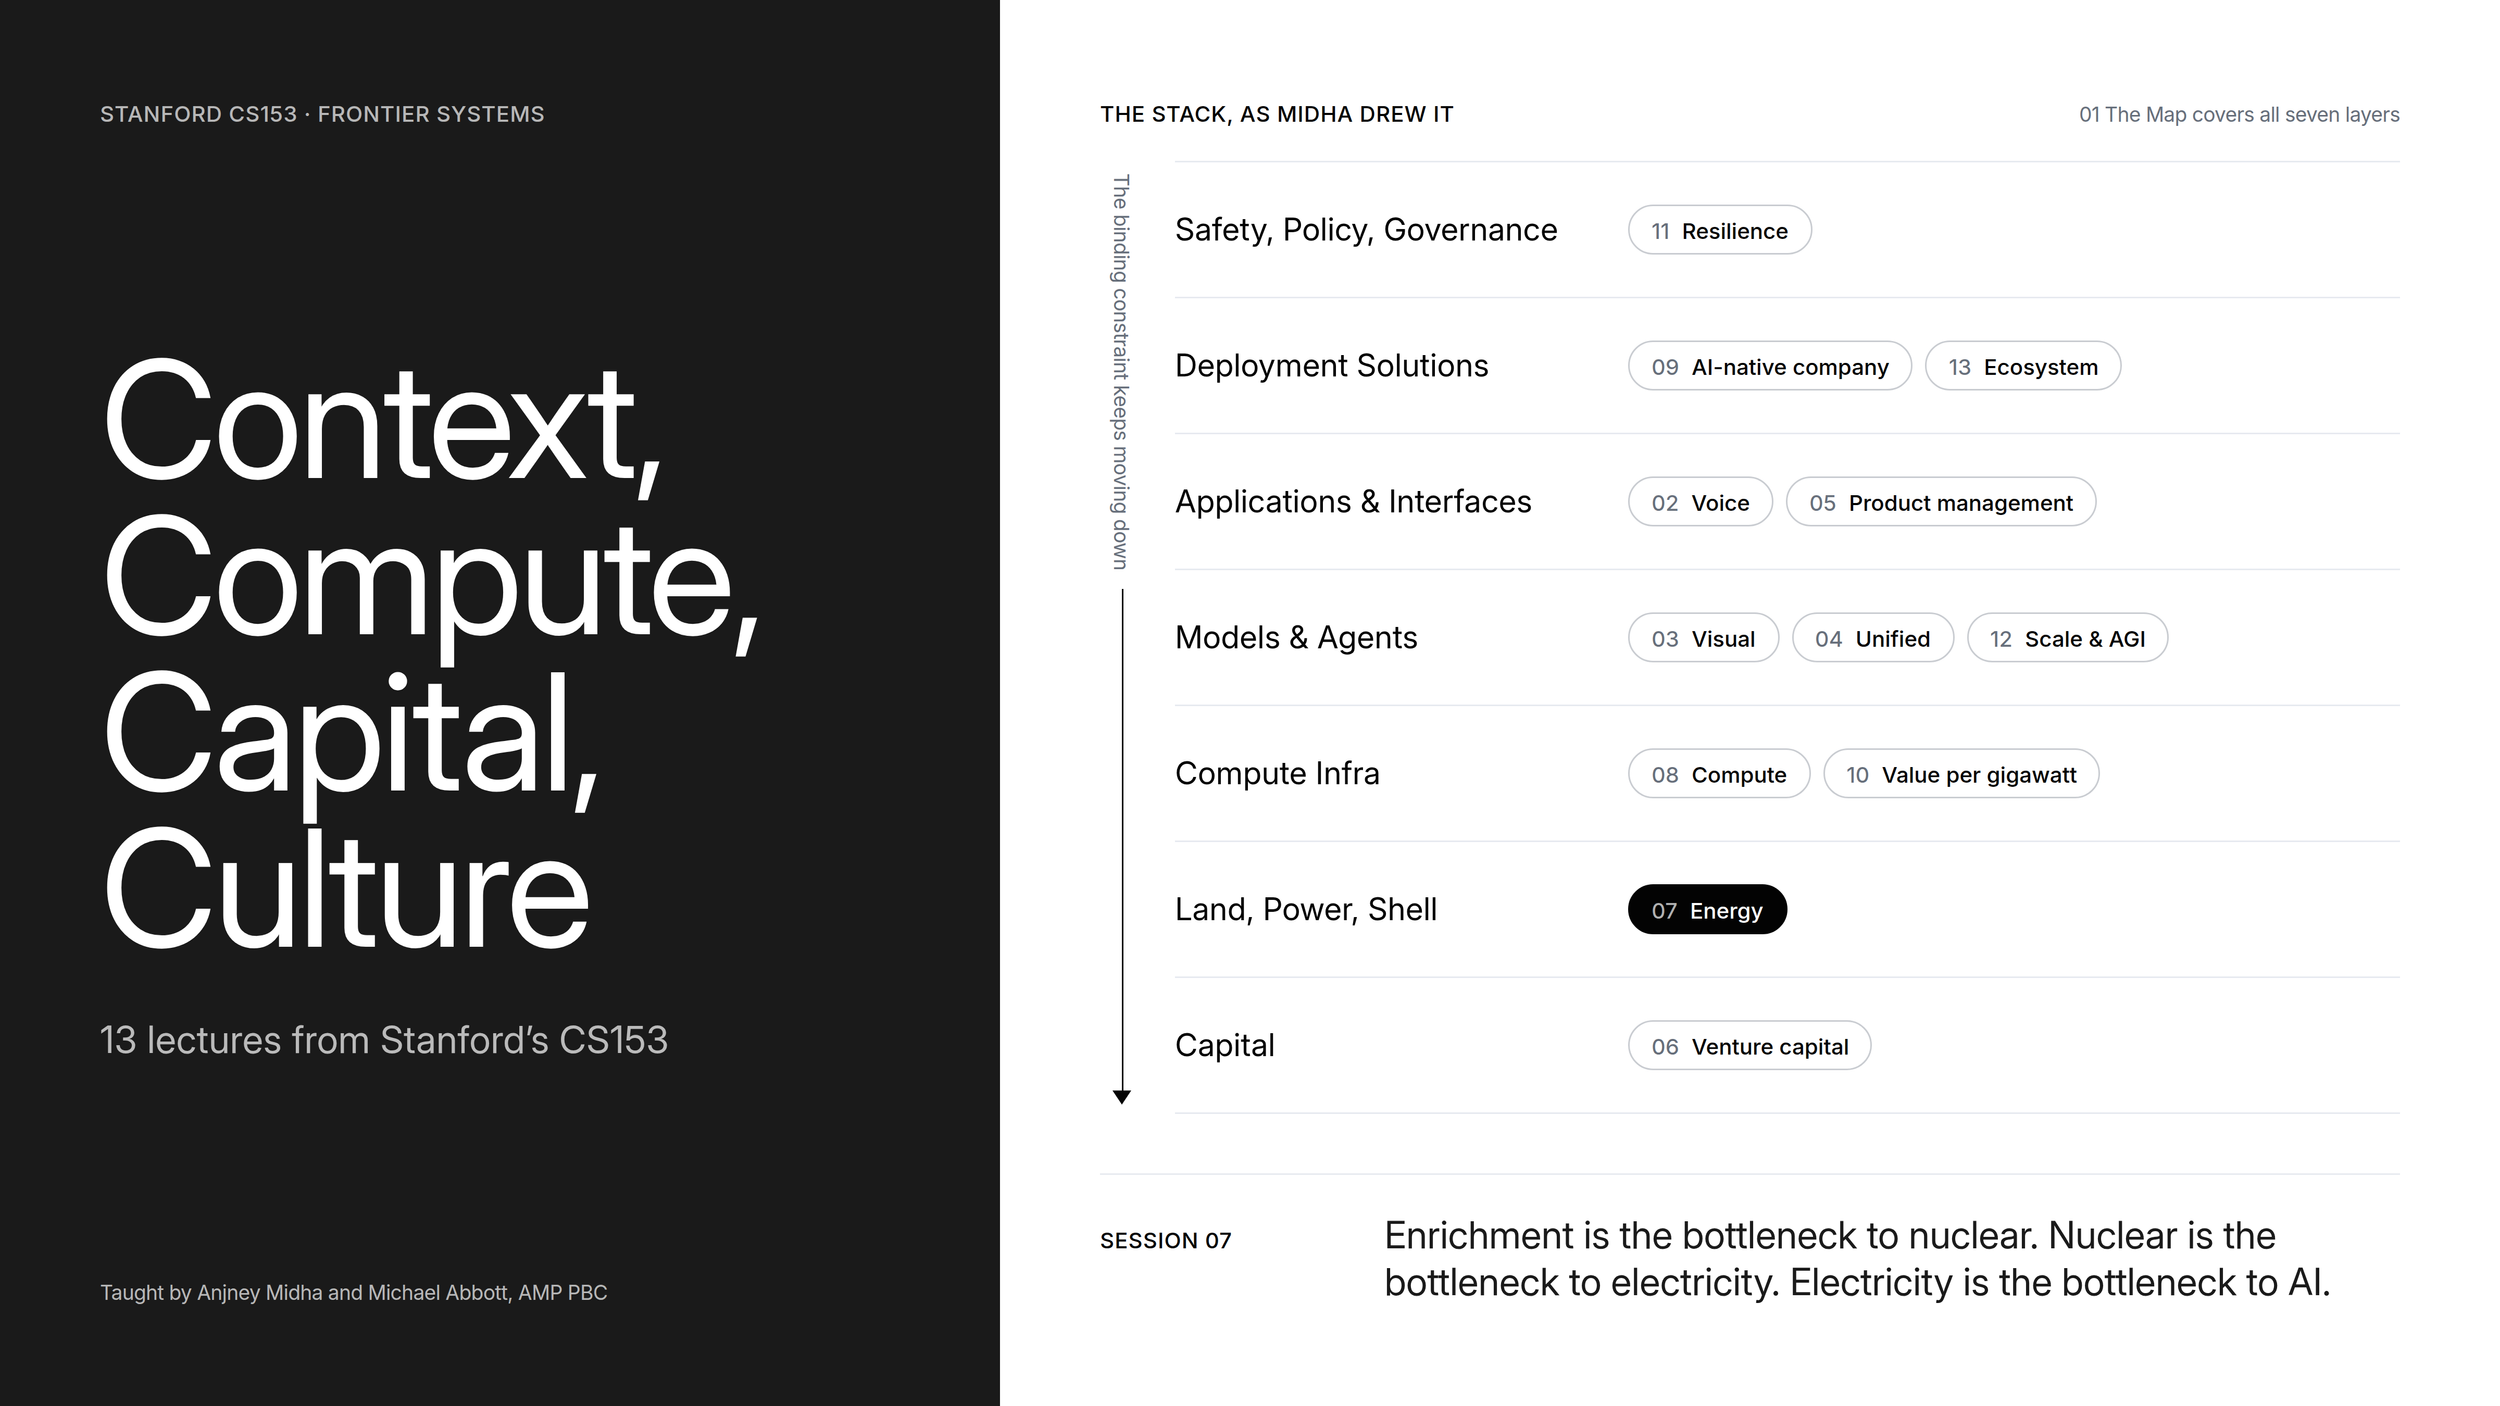
Enrichment is the bottleneck to nuclear. Nuclear is the bottleneck to electricity. Electricity is the bottleneck to AI. That slide came from the 7th of 13 sessions in Stanford's CS153: Frontier Systems. A course about frontier AI spent its midpoint on uranium. I worked through all 13 in September 2026, from Anjney Midha's opening map of the stack to guests from ElevenLabs, NVIDIA, OpenAI and Microsoft. This recap walks the course in order and reads it through the four lenses Midha gave the class: context, compute, capital and culture. It ends on the number I'll carry forward: Google depreciates its compute hardware over six years, and NVIDIA ships a new architecture every year.
Datacast Episode 94: Modern Metadata Management, Open-Source Adoption, and Early-Stage Culture with Mars Lan
Mars Lan is the co-founder and CTO of Metaphor Data, a startup that offers a Modern Metadata Platform to solve many complex organizational data challenges, such as data discovery and data governance. He also co-created the popular open-source project DataHub while working as the Tech Lead of the metadata team at LinkedIn. Mars received his Ph.D. in Computer Science from the University of California, Los Angeles.
Datacast Episode 79: Analytics Culture, Digital Contracting, and Data Angels with Jessica Cherny
Jessica Cherny currently runs the data analytics team at Ironclad, a series D digital contracting startup. As part of her job, Jessica builds out the data analytics function and provides analytics and data insights to inform business decisions for the product, customer success, engineering, sales, marketing, and operations organizations. Prior to joining Ironclad, she graduated from UC Berkeley as part of the university’s first cohort of Data Science majors.
Outside of work, Jessica is passionate about data mentorship and founded Data Angels -- a Slack community of women in data that provides resources, support, job opportunities, education, and community to its members.
Datacast Episode 41: Effective Data Science with Eugene Yan
Eugene Yan is a data scientist and writer. He works at the intersection of consumer data & tech to build machine learning systems to help customers and writes about effective data science, learning, and career. He's currently an Applied Scientist at Amazon, helping users read more and get more out of reading. Previously, he led the data science team at Lazada (acquired by Alibaba in 2016), working on e-commerce ML systems (e.g., ranking, automation, fraud detection).